duckdb-vectors
A frugal, embeddable semantic-search building block for agentic systems — hybrid vector + exact-token search over a local DuckDB file, no external vector database.
duckdb-vectors is a python package that facilitates the implementation of small-scale semantic search into any kind of agentic system, in 3 steps:
- chunk items and store their embeddings in a DuckDB database
- bake the database into the container that packages your agent
- search semantically using vector distances and BM25 in tens of milliseconds
When your agent deserves in-process semantic search
Most agents we build at work are specialists, not oracles. The honest requirement is small: semantic search over a modest, mostly-static corpus. Yet the reflex answer is large — stand up a vector database, run it as a service, wire the agent to it over the network. For a few thousand documents, that is a lot of moving parts to own, pay for, and keep alive. We wondered if there was a more frugal path.
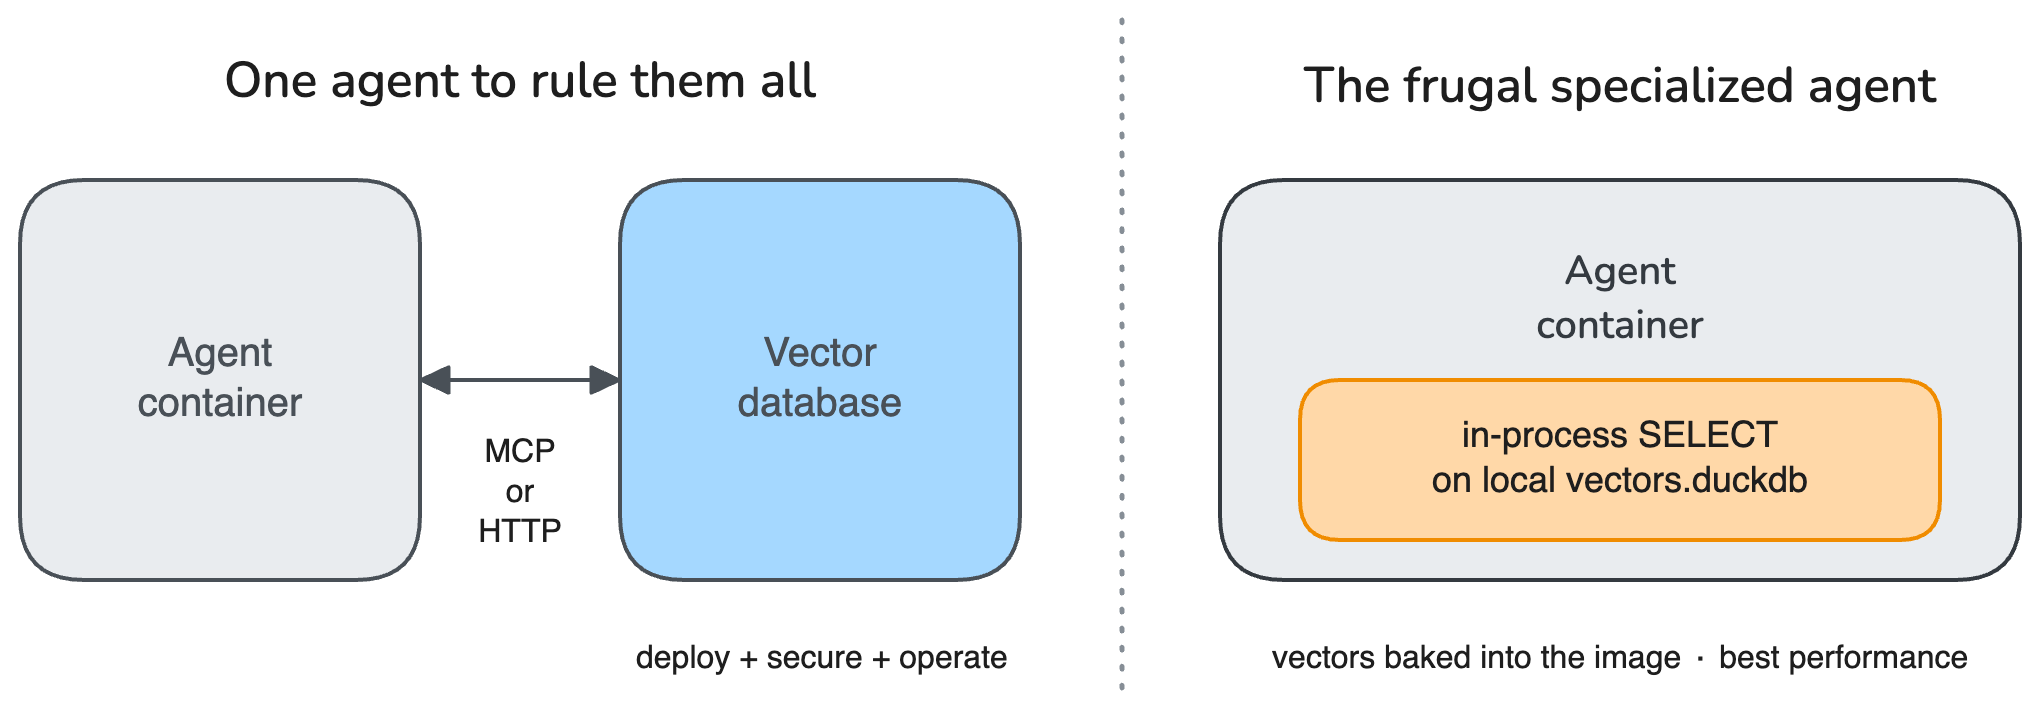
For the common case — a few thousand documents, read-mostly, packaged with one agent — you can skip the external vector database entirely. Index the corpus into a single DuckDB file, bake that file into the agent's container image, and answer semantic queries with a local function call in milliseconds. No MCP, no network round-trip. We packaged this pattern as duckdb-vectors, a compact open-source Python package.
For the engineering model behind "in milliseconds" — a fair latency comparison against a remote MCP and how much data reasonably fits in one container — see the performance guide.
Data architecture decisions and facts
A few deliberate choices shape how duckdb-vectors retrieves, and they are backed by measurement rather than assumption:
- One DuckDB file is one index, baked read-only into the agent's container image — no external vector database and no network hop on the query path.
- Indexes Markdown and PDF out of the box: a composite chunker dispatches each file by MIME type — Markdown is split on headings, PDF is read per page with a local OCR fallback for scanned pages — in one pass over a mixed folder (see Chunking backends). Other formats are a small chunker extension point.
- Hybrid retrieval: a brute-force exact cosine scan (
array_cosine_distanceover aFLOAT[256]ARRAY column at the default dimension — the width follows the chosen embedding model) fused with a BM25 exact-token scan via Reciprocal Rank Fusion. The BM25 index is built without stemming or stopwords on purpose, for language-agnostic exact-token matching. - No ANN index by default: the schema is HNSW-ready (a fixed-size ARRAY column), but the default path is brute force, because measurement shows HNSW is not worth the recall and persistence cost at the package's target scale.
- Local embedding by default (offline, in-process); cloud embedding (Bedrock Titan) is opt-in.
Measured on a MacBook Pro M1 (2021): ~27 ms p50 retrieval over a 1,000-chunk index at the 256-dim default, fully in-process — versus a network round-trip for a hosted vector database. Model and dimension are the lever on both latency and storage: the static 256-dim default embeds the query in ~0.3 ms, while a larger fastembed: tier or an hf: model (the loader now runs real models like Qwen3-Embedding and EmbeddingGemma) trades speed and file size for relevance. The measured per-model ladder, the full latency breakdown, the HNSW comparison, and the network-versus-in-process boundary are in the performance guide.
Use cases
duckdb-vectors has been designed for following use cases:
Retrieval-Augmented Generation (RAG) powered by thousands of static documents — You do not see the need for an external vector store or knowledge base. You prefer a composable toolchain over fat frameworks. You are looking for extremely fast responses. Turn an existing markdown folder into a RAG agentic capability.
Select skills exposed to your agents — The toolbox of your agent is growing exponentially. You create a tool for selecting appropriate skills instead of exposing all of them. In addition, each tool comes with attributes that should be considered during the search. Add a registry of hundreds of skills selected by semantic search.
Chat with your LLM-wiki — You have setup an agentic knowledge base that is managed and enhanced incrementally. It consists of a growing set of Markdown pages, that deserves careful chunking and embedding for response relevance. You want a simple complementary toolchain for chatting with your Wiki. Leverage an LLM-managed wiki into an agent.
Quick start
Get duckdb-vectors from the PyPI repository:
$ pip install duckdb-vectors # install once, batteries includedIndexing a set of Markdown pages directly from the command-line. This produces a single DuckDB file:
$ duckdb-vectors index ./docs            # index a folder of markdown and PDF
$ duckdb-vectors report                  # report on database content
$ duckdb-vectors search "my question"    # hybrid search
You can also index content dynamically from the harnessing code. This is required if the agent gets new skills dynamically for example.
Then perform semantic search from within your python code:
from duckdb_vectors import VectorStore

store = VectorStore()

for hit in store.query("how does an embedded database work?", top_k=3):
    print(hit.score, hit.chunk.chunk_id, hit.chunk.text)
Customization
This section marks the boundaries of the package: what you can adapt out of the box, and where the extension points are for builders who want to contribute.
The default configuration of duckdb-vectors makes it workable out of the box. But you do have multiple options for adapting it to your specific requirements:
Choose your harnessing framework, or create your own.
duckdb-vectorsfocuses on semantic search. Pass a string, and it returns matching chunks. Use them as you want.Frontmatter headers of Markdown pages are injected as JSON objects. Each attribute can be considered in SELECT statements in addition to semantic search. Metadata is returned along with each chunk.
Choose your embedding model by string. The default is a compact 256-dimension multilingual model; step up the
fastembed:dimension ladder (384 / 768 / 1024) for more relevance, load any Hugging Face ONNX repo withhf:<repo-id>, or embed in the cloud withbedrock:titan. See Embedding backends below.Implement your own chunking class, that is fully adapted to your knowledge base. We have focused on Markdown and PDF files. You may have other kinds of documents to ingest.
Adding an embedding backend or a chunker is a great first contribution — the registries are built for it. See CONTRIBUTING.md to get started.
Documentation
Pick the entry point that matches where you are:
New to
duckdb-vectors? Read the primitive for understanding the architecture and building blocks, then the guide for the straightforward developer workflow.Building a specific capability? Follow a step-by-step procedure: RAG answering machine, LLM wiki to RAG, or semantic skills search.
New to DuckDB? See the DuckDB workbook.
Packaging an agent? See the Containerized agent guide.
Deploying on AWS? See the Bedrock AgentCore guide, or the Lambda guide.
Contributing or developing? Start with CONTRIBUTING.md, then the developer workbook for prerequisites, setup, and the full workflow.
Configuration
Settings resolve with the precedence: explicit argument > DUCKDB_VECTORS_* environment variable > default.
| Setting | Argument | Environment variable | Default |
|---|---|---|---|
| Database path | db_path | DUCKDB_VECTORS_DB_PATH | vectors.duckdb |
| Embedding backend | backend | DUCKDB_VECTORS_BACKEND | fastembed:minishlab/potion-multilingual-128M |
| Read-only | read_only | DUCKDB_VECTORS_READ_ONLY | false |
Embedding backends
The selection of a backend for embeddings is resolved from a string: a name:variant pair (fastembed:<model>, hf:<repo-id>, bedrock:titan) or a bare name (hashing). The default is fastembed:minishlab/potion-multilingual-128M, a static multilingual model that keeps vectors and the DuckDB file as small as possible while serving international docs. The registry is contributor-extensible — register open or closed, local or cloud backends without touching the core:
from duckdb_vectors import register_embedder

register_embedder("mybackend", lambda variant: MyEmbedder(variant))
The fastembed: backend runs a bundled ONNX model with no torch dependency; pick the dimension tier that fits your relevance/size budget. The hf:<repo-id> backend is core (no extra install) and loads any Hugging Face repo that ships ONNX weights, running them through the ONNX runtime fastembed already vendors.
| Backend | Spec | Dimensions | Use for |
|---|---|---|---|
| fastembed potion (static, multilingual) | fastembed:minishlab/potion-multilingual-128M | 256 | default; smallest DB, international docs |
| fastembed MiniLM (multilingual) | fastembed:sentence-transformers/paraphrase-multilingual-MiniLM-L12-v2 | 384 | balanced multilingual relevance |
| fastembed mpnet (multilingual) | fastembed:sentence-transformers/paraphrase-multilingual-mpnet-base-v2 | 768 | higher multilingual relevance |
| fastembed e5-large (multilingual) | fastembed:intfloat/multilingual-e5-large | 1024 | strongest multilingual relevance |
| fastembed bge-small (English) | fastembed:BAAI/bge-small-en-v1.5 | 384 | English-only, compact |
| fastembed bge-large (English) | fastembed:BAAI/bge-large-en-v1.5 | 1024 | English-only, strongest |
| Hugging Face ONNX (any repo) | hf:<repo-id>, e.g. hf:onnx-community/Qwen3-Embedding-0.6B-ONNX | probed | any HF repo shipping ONNX weights |
| Bedrock Titan | bedrock:titan | 1024 | cloud embedding |
| Hashing (deterministic, no deps) | hashing | 384 | tests and CI only, not relevance |
Chunking backends
Indexing uses the composite chunker by default: index_folder dispatches each file to the registered chunker whose declared MIME type matches the file's mimetypes.guess_type. Each chunker claims one or more MIME types rather than a file suffix, so .md and .MD (both text/markdown) go to the same chunker.
Contributing a new file type means writing a FilesystemChunker subclass that declares its mimetypes frozenset and a chunk_file method, then registering it. A newly registered chunker participates in the composite automatically:
from duckdb_vectors import register_chunker

register_chunker("mychunker", lambda variant: MyChunker(variant))
For a code-level override, pass an explicit chunker instance to index_folder (for example index_folder(store, folder, chunker=PdfChunker())) to index only that format.
| Chunker | MIME type(s) | Use for |
|---|---|---|
| MarkdownChunker | text/markdown (.md, .markdown) | heading-scoped sections with word-window splitting |
| PdfChunker | application/pdf (.pdf) | per-page text with a local OCR fallback for scanned pages |
| CompositeChunker | dispatches by MIME type | default; indexes a mixed-type folder in one pass |
Metadata-aware search (injectable ranking SQL)
duckdb-vectors has built-in SQL statements for searching in DuckDB database. This is good enough for common cases. In addition, you can provide your own SQL statements for refining to your exact needs.
For example:
Adapt the search to a given audience. You want to serve both customers and your staff from the same agent. The distinction is carried by the JWT token that reaches the agent. The searching code can extract either "customer" or "staff" from the token, and inject this in the SQL statement, so that only the matching set of pages is considered.
Tweak the ranking algorithm. You want to decay progressively the aging documentation pages, so that fresh content gets better ranking than oldies. The searching code can integrate the modification date from meta-attributes and decay the basic ranking accordingly.
Each ranking signal — vector and BM25 — runs a DuckDB SELECT that returns chunk_id best-first. The store collects the ids and fuses them with RRF. You can override either SELECT to restrict in-scope chunks (a WHERE over metadata) or to apply a decay factor on aging documents (a reshaped ORDER BY). When you provide no override, built-in defaults reproduce the standard behavior.
Templates use these substituted tokens: {table}, {distance} (vector only), {bm25} (text only), {top_k}. The search text is available as the bound parameter $q. Standard columns are in scope: metadata, source, title, stamped_at, text.
Overrides can be set once (shared across queries) via Settings or DUCKDB_VECTORS_VECTOR_SQL / DUCKDB_VECTORS_TEXT_SQL, or passed per call. Precedence is per-call > settings > default. A custom SELECT owns its own WHERE and supersedes the convenience filter dict for that signal.
Here is an example where the search is limited to policy pages, aka, where kind: policy:
scoped = (
    "SELECT chunk_id FROM {table} "
    "WHERE json_extract_string(metadata, '$.kind') = 'policy' "
    "ORDER BY {distance} LIMIT {top_k}"
)
store.query("retention rules", vector_sql=scoped, text_sql=scoped)
Here is a example for decaying aging documents (older chunks sink; age_days lives in metadata):
decayed = (
    "SELECT chunk_id FROM {table} "
    "ORDER BY {distance} "
    "* (1 + CAST(json_extract_string(metadata, '$.age_days') AS DOUBLE) "
    "/ 365.0) "
    "LIMIT {top_k}"
)
store.query("latest guidance", hybrid=False, vector_sql=decayed)
The injected SELECT is caller-authored SQL run against your own database (opened read-only in the serving path); the query text and embedding are parameter-bound.
Design note: lexical search without stemming
Hybrid search here fuses semantic (vector) retrieval with a BM25 lexical signal, but the BM25 index is built deliberately with stemmer = 'none' and stopwords = 'none'. This is a considered choice, not an oversight.
Semantic search already covers meaning, paraphrase, and synonyms, and it does so across languages. Traditional stemmed full-text search (Porter stemming plus a per-language stopword list) adds compute and storage, ties the index to one language, and — in our prior benchmarks on comparable corpora — did not improve relevance enough to justify that cost once semantic retrieval was in place.
What vectors do not handle well is exact short tokens: acronyms, product codes, identifiers, and single-keyword queries. That is precisely where a lexical signal earns its keep. So the BM25 index is kept, but as a language-agnostic exact-token match: ESRS finds ESRS, while run does not conflate with running. The two signals are complementary — vectors for meaning, exact-token BM25 for the literal strings vectors miss.
A developer who wants classic stemmed full-text behavior can still have it: build their own FTS index and supply a custom text_sql (see above). The default simply does not impose stemming on everyone.
Why?
You are right, trillions of solutions exist for semantic search. So, why bother?
Because we are frugal.
We won't embrace a fat framework, but limit our code base and dependencies to the strict minimum. We just want to install and import a dedicated PyPI package that does one thing well.
We won't delegate via the network a search across some thousands of items. A local function call is by far the fastest path to relevant answers. DuckDB is a perfect fit for such in-process use case. See
examples/skill_registry.py.We won't use stemming search at all. Semantic search for sentences and exact matches for keywords cover our needs.
We won't externalize a read-only vector database or knowledge store for some thousands of items. This should be baked into the file system of the agent itself. DuckDB just needs a single database file, this is just what we need.
We won't introduce separate baking for the code and for data, since modern agents rely on Docker images anyway. See
examples/Dockerfile.We won't invest on non-differentiating features. Trusted harnessing will come from boring technologies.
We did our homework, as reflected in the Alternatives section. It appears, in the end, that no python package was available to cover our frugal needs.
Alternatives
duckdb-vectors is not the only way to put vectors in DuckDB. The projects below overlap with it; each is a reasonable choice if its shape fits your need better than ours. Our goal is narrow on purpose: a small, framework- agnostic, read-mostly utility that bakes an index into a container image and answers in tens of milliseconds, with pluggable embedding and chunking and an S3-Vectors-flavored surface. Where a project pulls in a framework, a service, or a broader scope, we point you to it rather than compete with it.
llama-index-vector-stores-duckdb — the official LlamaIndex integration that stores embeddings in DuckDB. Great if you are already building on LlamaIndex, because it plugs into that data model, retrievers, and query engines. We stay framework-agnostic: no LlamaIndex
Node/Documenttypes to adopt and no framework runtime to carry into the container.vectorwrap — a universal wrapper that switches one vector API across Postgres, MySQL, SQLite, DuckDB, and ClickHouse. Pick it when backend portability is the point. We go the opposite way: one backend (DuckDB), chosen deliberately, so we can lean on DuckDB-specific features (ARRAY columns, injectable ranking SQL) instead of a lowest-common-denominator API. It also expects you to bring your own embedding function; we ship pluggable embedders and markdown chunking.
microrag — the closest neighbour: a universal RAG library with ONNX-backed embeddings and DuckDB storage. If you want an end-to-end RAG library, it is a strong fit. We are not a RAG library — we deliberately stop at retrieval (store, index, search) and leave generation, prompting, and LLM orchestration to the harness, so the component composes into any framework rather than owning the pipeline.
Docker Agent RAG toolset — the built-in
ragtoolset of Docker Agent (cagent): declare a knowledge base underrag:in the agent config and any agent searches your documents before answering, no separate retrieval package. Reach for it when Docker Agent is already your harness and you want retrieval wired in-runtime. We stay harness-agnostic:duckdb-vectorsis a standalone library you call from any framework (or from Docker Agent itself viaduckdb-vectors mcp, see the Docker Agent guide), so the index and the retrieval surface are not tied to one agent runtime.duckdb
aicommunity extension — an extension that calls embedding and chat providers from inside SQL. Reach for it when you want embeddings generated in the database and don't mind the provider wiring living in SQL. We keep embedding in Python so the same code runs offline in CI and against a cloud provider in production without SQL-level credentials.sqlrooms-rag — prepares and queries DuckDB-stored embeddings for RAG, primarily for the SQLRooms framework (usable standalone too). A good fit inside that ecosystem; outside it, our standalone, dependency-light surface and container lifecycle are a closer match.
raghilda — a DuckDB-backed RAG store (from Posit) that can run fully in memory and search with BM25 when no embedding model is configured. Pleasant for quick local experiments. Our focus is the frozen, read-only, image-baked serving path and an S3-Vectors-flavored API rather than an in-memory exploration store.
dvs — a DuckDB + OpenAI vector similarity search service. Choose it if an OpenAI-tied service is what you want. We default to local, offline embeddings and treat cloud providers as an opt-in, keeping the base install slim and CI-friendly.
Contributing
Contributions are welcome — adding an embedding backend or a chunker is a great first pull request. See CONTRIBUTING.md for the development setup, project principles, and pull-request guidelines.
License
MIT.